무슨 발표인가
- SAM 3으로 텍스트 프롬프트 기반 객체 감지·추적
- SAM 3D로 단일 이미지 기반 3D 재구성
- Segment Anything Playground에서 실험 가능
원문 (영어)
Today, we’re excited to announce SAM 3 and SAM 3D, the newest additions to our Segment Anything Collection . SAM 3 enables detection and tracking of objects in images and video using text and visual prompts, and SAM 3D enables 3D reconstruction of objects and people based on a single image.
You can experiment with both models now on our new platform, Segment Anything Playground. These advancements will help us build the next generation of creative media tools, simplifying video editing and giving us new ways to interact with and understand the visual world.
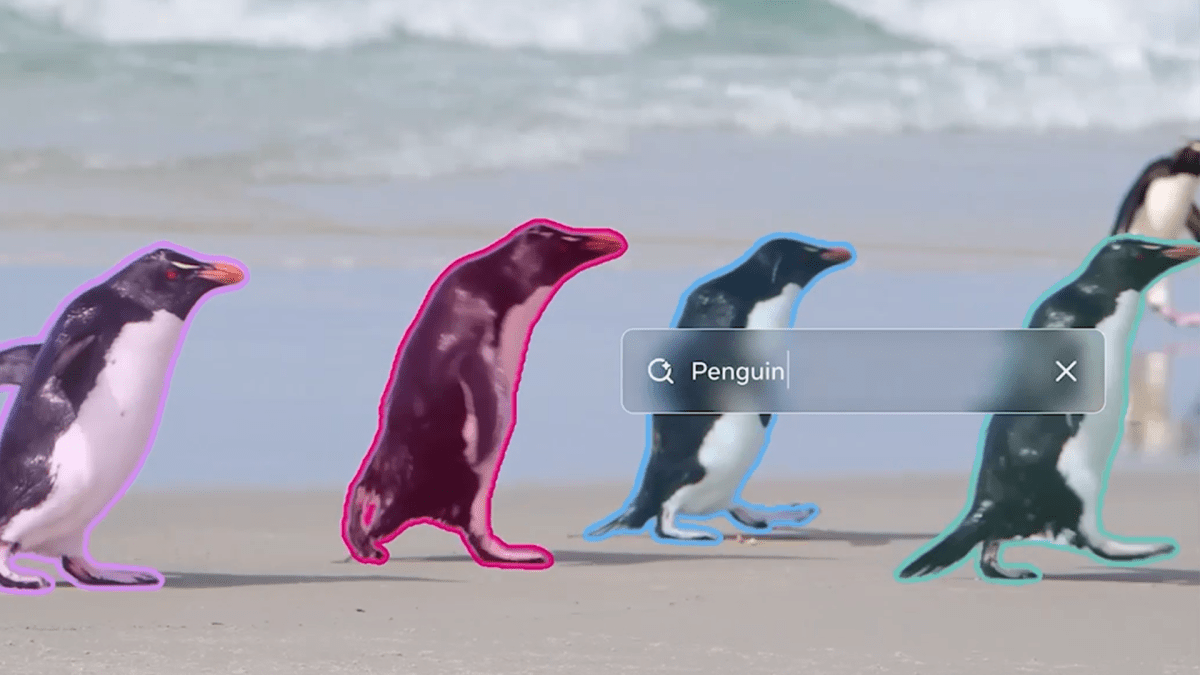
Say What You Mean SAM 3 makes it easy to detect, segment, and track objects in images and video — functions that can be used to edit and transform videos and images. SAM 1 and 2 supported segmentation based on visual prompts, and now, SAM 3 enables you to segment using detailed text prompts describing the objects you want to segment.
Traditionally, AI models have struggled to link language to specific visual elements in images or videos. Existing models typically have a fixed set of text labels and are able to segment simple concepts like “bus” or “car,” but struggle with more detailed concepts like “yellow school bus.”
SAM 3 overcomes this limitation, accepting a much larger range of text prompts. Type in “red baseball cap” and SAM 3 will segment all matching objects in the image or video. SAM 3 can also be used with multimodal large language models to understand longer, more complex text prompts, like “people sitting down, but not wearing a red baseball cap.”
We’re using SAM 3 to build a new generation of creative media tools. In Edits, our video creation app, we will soon introduce effects that creators can apply to specific people or objects in their videos.
원문: Meta Newsroom — "New Segment Anything Models Make it Easier to Detect Objects and Create 3D Reconstructions" (2026-08-05) 공식 원문: https://about.fb.com/news/2025/11/new-sam-models-detect-objects-create-3d-reconstructions/